
I Built a Zero-Build Blog: Just Markdown and git push
Intro
Every "simple" blog I tried wanted the same thing from me first: install a static-site generator, learn its templating language, run a build, then babysit a deploy pipeline. I just wanted to write a Markdown file and have it show up online.
So I built the smallest thing that does exactly that — and nothing else. No Hugo, no Jekyll, no Astro, no node_modules, no CI to stare at. You add a folder, you git push, and the post is live. This is the blog you're reading right now, and this post is about how it works.
The whole idea fits in one sentence: the Git repo is the website.
1. The frustration that started it
A blog is, structurally, almost nothing: a list of posts, and a way to render one. Yet the standard advice turns that into a toolchain — a generator, a theme system, a build command, a deploy action, and a node_modules folder heavier than everything you'll ever write.
Every one of those is a thing that can break between you and hitting "publish." I wanted the gap between I wrote something and it's online to be a single git push. Nothing to build, nothing to wait on, nothing to debug at 1 a.m. because a generator bumped a major version.
2. The trick: let the browser do the work
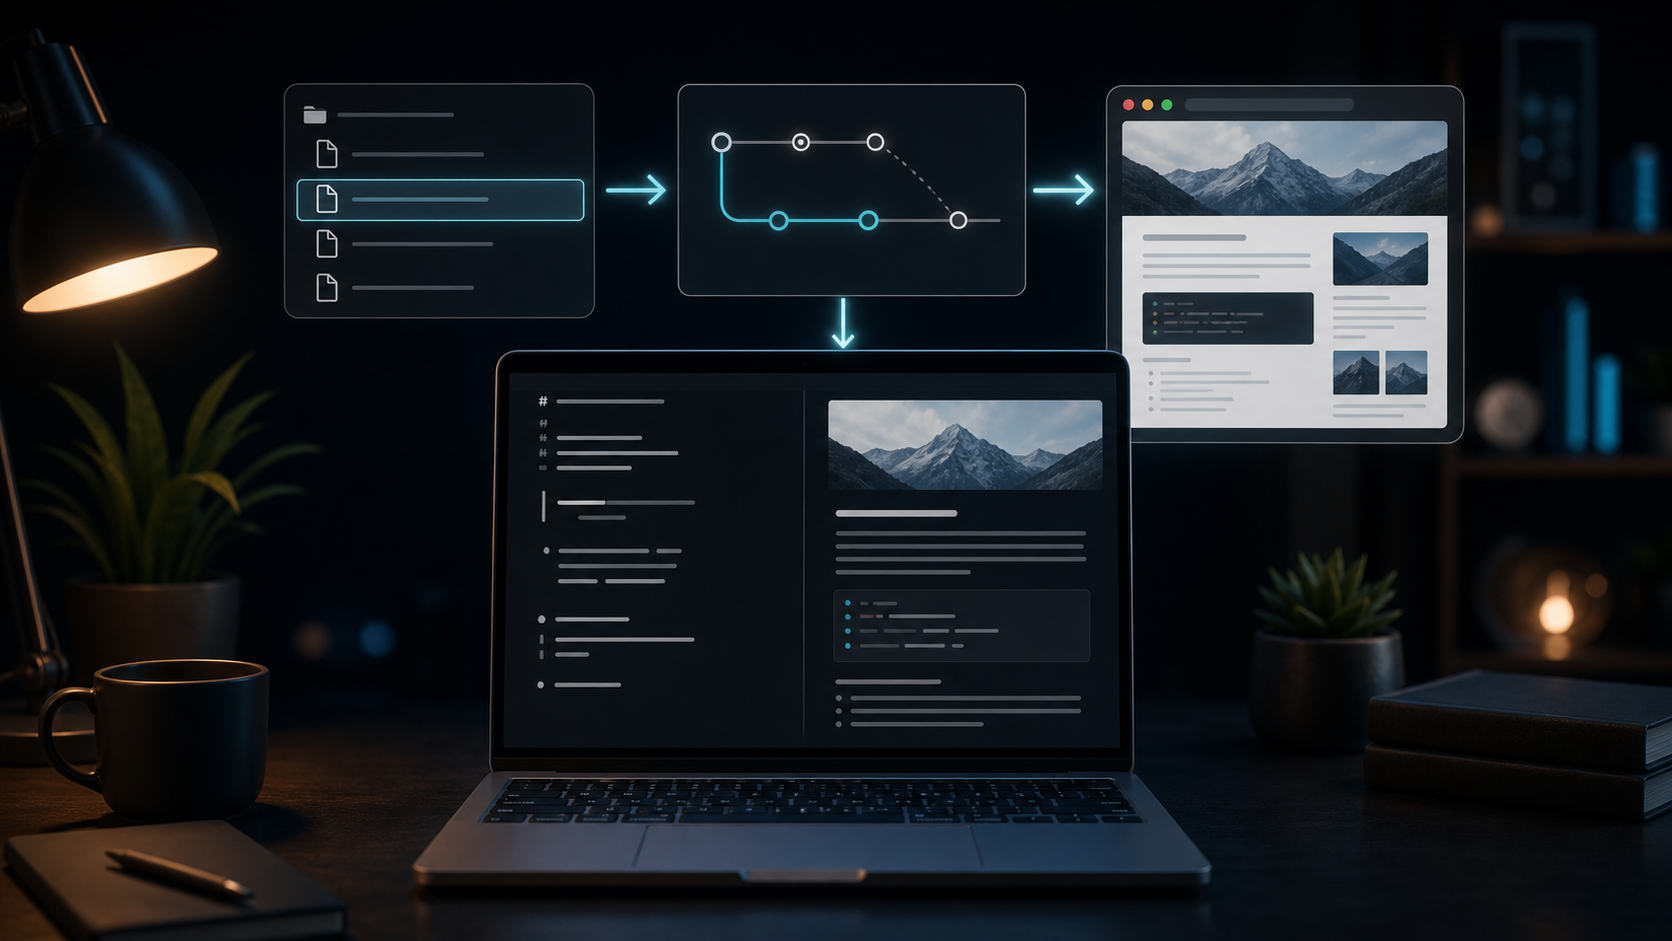
Instead of building HTML ahead of time, the site builds itself in the browser, on demand:
   write Markdown              git push                 GitHub Pages
  posts/<date>-slug/   ──────────────────►   main   ──────────────────►   index.html + assets/
        index.md                                                                 │
                                                                                 │  in the browser
            ┌─────────────────────────────────────────────────────────────────────┘
            ▼
   list posts (title / date / summary / tags)
   posts/<dir>/index.md ──►  marked + DOMPurify + highlight.js  ──►  rendered article
There is no server of mine in this picture. GitHub Pages serves a static index.html plus a ~400-line vanilla-JS engine. The engine:
- Finds the posts by reading the repo's
posts/directory. - Fetches the chosen post's
index.mdas raw text. - Renders it client-side with marked (Markdown → HTML), sanitizes the result with DOMPurify, and colors code with highlight.js.
Libraries load from a CDN; the app shell caches like an installed app. That's the entire architecture. The "database" is the folder tree.
3. What you get for free
Because the post list is derived, not hand-maintained, a lot of housekeeping just disappears:
- 🗂 Auto index — drop a post folder, it appears on the home page, newest first. No list to edit.
- 🔗 Auto prev/next — inter-post navigation is generated from the post order.
- 🖼 Relative images — write
images/diagram.pngand the engine resolves it per post, so two posts can both have animages/cover.pngwithout colliding. - 💬 Comments — GitHub Discussions via Giscus, no third-party tracker.
- 🌓 Dark mode that follows the system theme, and light/dark-aware syntax highlighting.
Writing a post is just:
posts/
└─ 2026-06-26-zero-build-blog/
   ├─ index.md      # frontmatter + body
   └─ images/       # referenced as images/x.png
---
title: My Post
date: 2026-06-26
summary: One line shown on the home-page card.
tags: [blog, vanilla-js]
---

The body starts here…
Push it. Done.
4. The one pit I fell into: the GitHub API rate limit
The first version was even purer: it listed posts live through the anonymous GitHub Contents API at page load. Beautiful in theory — zero stored state, the directory listing was always the source of truth.
Then the home page started returning 403 for some visitors.
The anonymous GitHub API is rate-limited to 60 requests per hour per IP. On shared or carrier-grade-NAT networks (and to anyone who refreshed a few times), that budget evaporates, and the listing call fails. A blog whose home page sometimes just doesn't load is not a blog.
The fix keeps the "repo is the source of truth" spirit without paying the API tax on every page view: a tiny zero-dependency script, scripts/gen-posts.mjs, scans every posts/<slug>/index.md, parses its frontmatter, and writes a static posts.json. The engine reads that file first — no API call, no rate limit, no 403.
And to keep the author's promise intact ("just push"), a GitHub Actions workflow runs that script on every push and commits the regenerated posts.json. So the index is still derived from the posts — the derivation just moved from the visitor's browser, every time to CI, once per push. The frontmatter parser in the script is deliberately identical to the one in the client engine, so what CI indexes and what the browser renders can never drift apart.
5. Bilingual without a framework
Each post can ship two files: index.md (English, the default) and index.zh.md (Chinese). Frontmatter declares the relationship:
lang: en
translations: [zh]
The engine sees translations and shows a language toggle; clicking it swaps to index.zh.md. No i18n library, no routing config — two files and two lines of frontmatter.
6. Honest trade-offs
This approach is deliberately narrow, and it's worth being clear about the costs:
- The repo must be public. The engine (and the no-build ethos) assumes anyone can fetch the raw Markdown. Private blogging is not what this is for.
- Rendering is client-side. First paint waits on JS + CDN libraries. For a text blog this is imperceptible; for a latency-critical or SEO-maximalist site, prerendering would win.
- Mainland-China reach is still on the roadmap — GitHub Pages can be flaky there, so a Cloudflare Pages / self-hosted mirror is the next step.
None of these dent the core win: the distance from idea to published is one commit.
7. Use it yourself
It's MIT-licensed (the engine, not my words). Fork it, point CONFIG.repo in assets/app.js at your repo, enable GitHub Pages on main, and you have a blog where writing a post means writing a file.
→ github.com/byzosc/zero-build-blog
If it saves you from spinning up yet another static-site generator, a ⭐ means a lot.